
Engineering / Registry Metric Lab
Registry Metric Lab, when a join inflates enrollment
Can one extra site change the enrollment total? Three invented trials enrolled 500 people, and a join to their sites reports 600 while the trial count still says three.
- Teaches A real defect, found and fixed in TrialCat
- Built with Python standard library and SQLite
- Tests 46 passing
- Data Invented trials. No patient data
Teaching demo · The Real Cat Labs · November 2026
The question
Can one extra site change the enrollment total?
A registry lists each trial once and each of its sites once. Join the two to filter by country, and a trial with two matching sites comes back twice. The count of distinct trials still looks right. The enrollment sum has quietly counted that trial twice.
Registry Metric Lab teaches a real defect. We found it in TrialCat, our small public app for exploring clinical trial registry data, and fixed it there. The demo is a fresh explanation in standard-library Python that runs the flawed SQL and the corrected SQL side by side on invented records.
How it works
Count the trials first, then calculate
- Three invented trials They enrolled 500 people in all. One trial has two matching sites.
- The flawed query It joins trials to sites and then sums. The trial with two sites is counted twice, and the total reads 600.
- The corrected query It selects trial identities first and calculates each metric once per trial. The total reads 500.
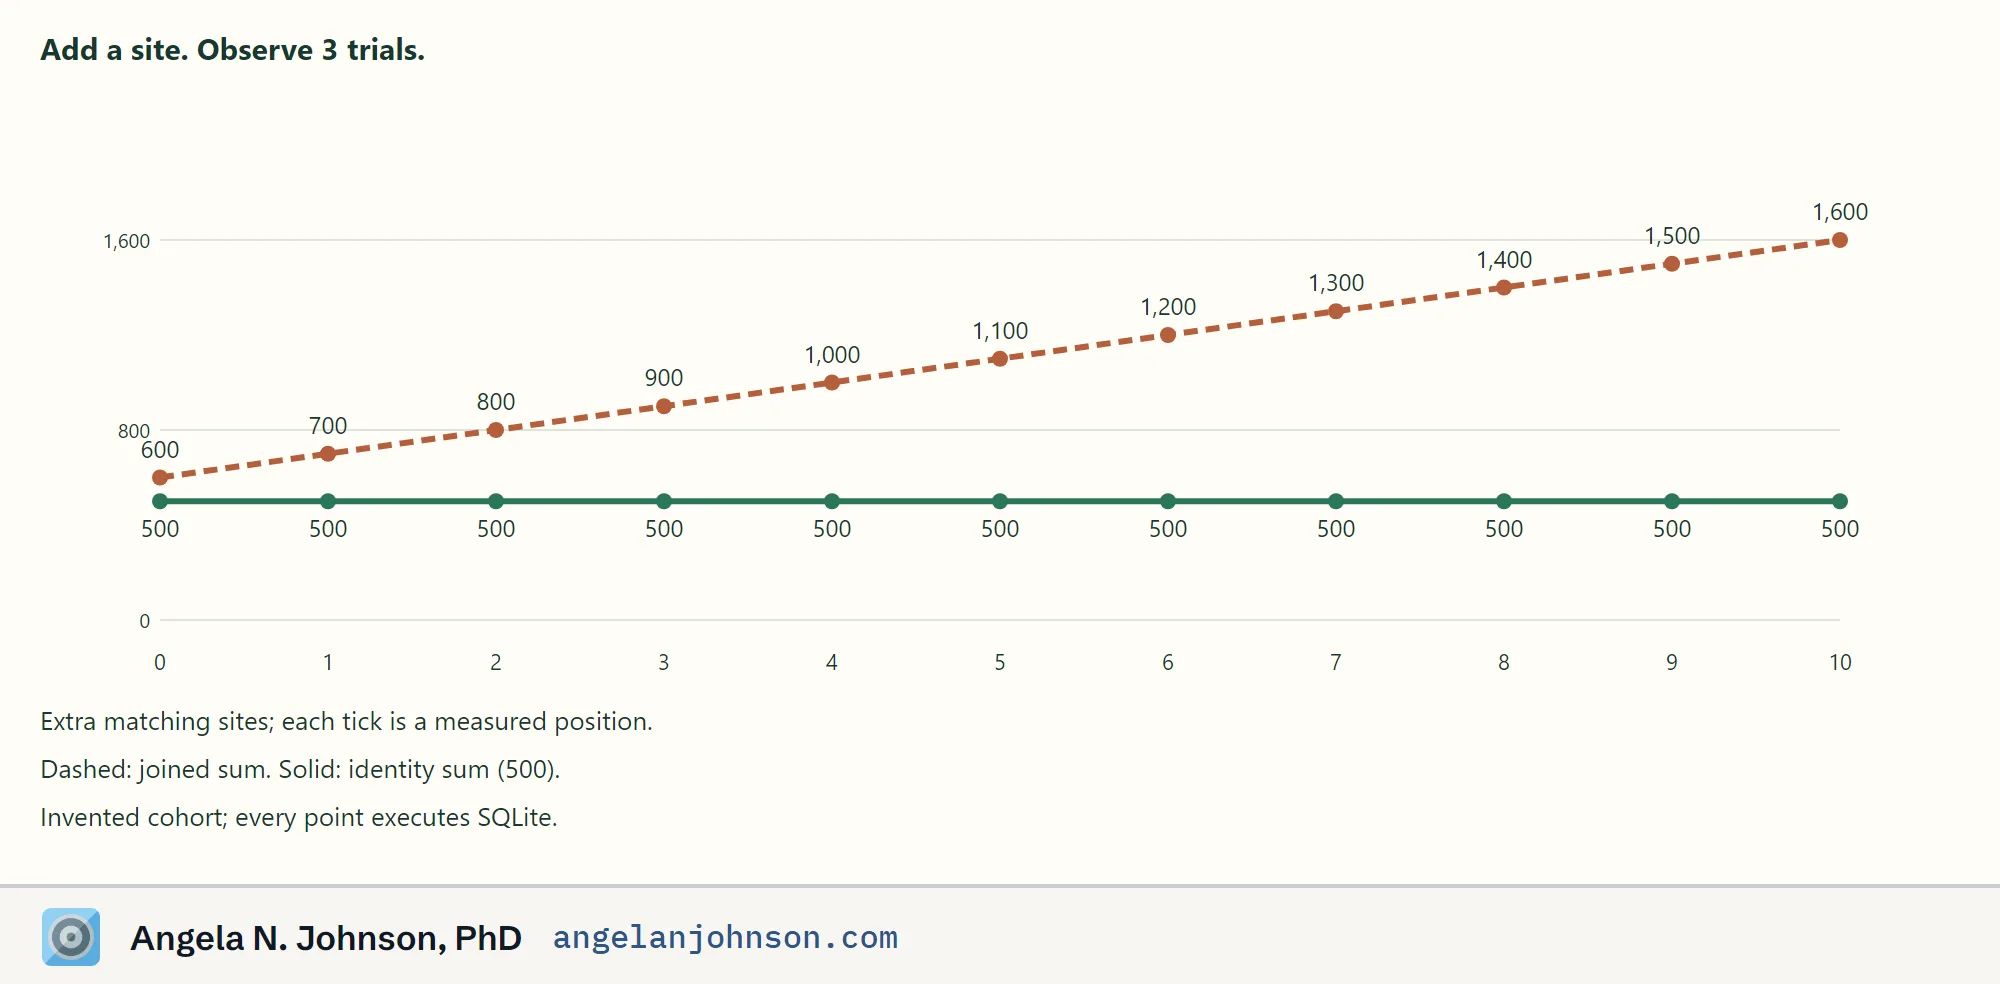
- The site dial Add up to ten more sites to one trial. The joined sum climbs from 600 to 1,600, and the correct total stays at 500.
- The evidence Every chart is drawn from the real SQLite queries, and the raw results keep every query, input, and sweep result.
Every record is invented. This is a deterministic engineering demonstration, not a live clinical trial analysis.
What it shows
The same three trials, two different totals
-
600 vs 500
A join inflates the sum
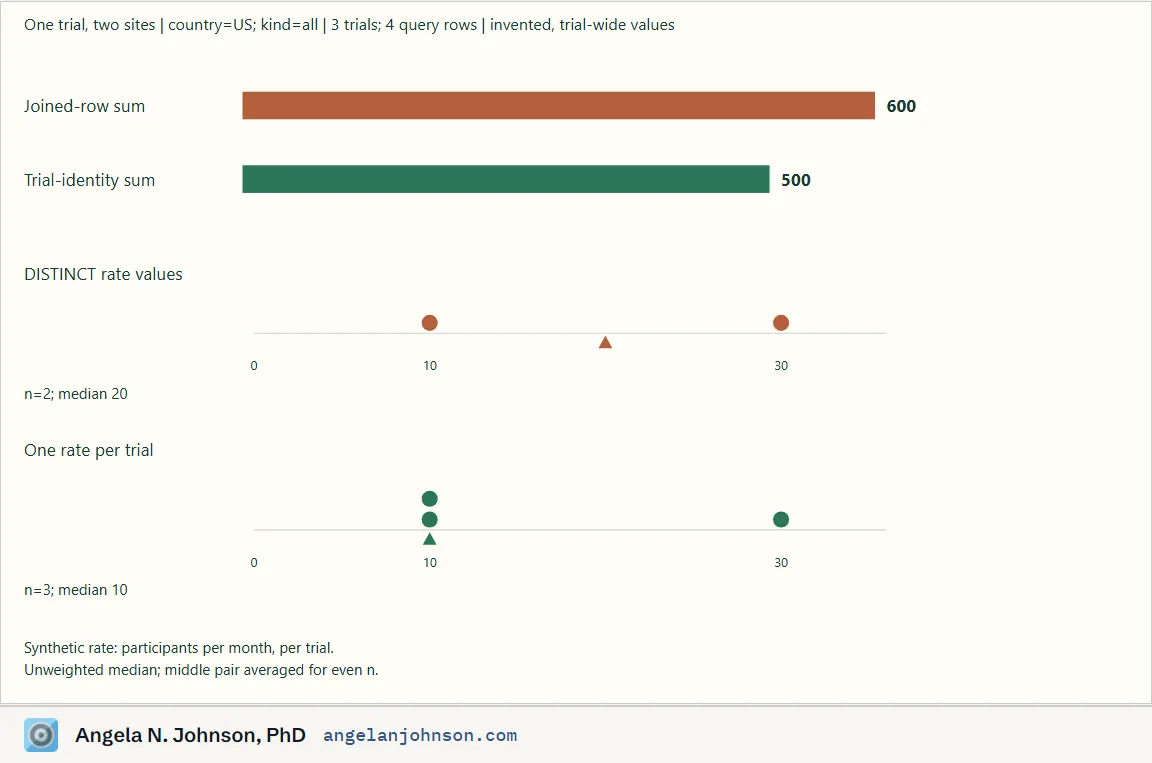
Joining trials to their sites reports 600 enrolled while the trial count still says three. Counting each trial once gives 500.
-
20 vs 10
Deduplication moves the median
Three trials have rates of 10, 10 and 30. Dropping the repeated value leaves two numbers and a median of 20. One rate per trial gives 10.
-
1,600
More sites, a bigger error
Ten extra sites on one trial push the joined sum to 1,600. The identity-correct total does not move.
-
870 vs 570
Two joins multiply
When the country map also joins interventions, matching rows multiply each other. In the six-trial fixture the US total reads 870 against a correct 570.
The evidence under the evidence
How the tests were tested
A test suite that passes says little until someone tries to break the code under it. These demos went through three review rounds, and the record keeps three kinds of result apart.
-
13 of 14
Held out, scored before repair
After the second repair, the reviewer wrote 14 new breaks aimed at the changed code. By the reviewer’s account, the implementer had not seen them. The tests caught 13.
-
167 of 176
Chosen by the reviewers, not the implementer
The tests caught 118 of these breaks before the repairs and 167 after. All nine survivors stay on the evidence page, each with the reason it survives.
-
32
Comment contracts, chosen by the implementer
Each names a small code change that would break it and the test that must then fail, and CI checks that on every push. All 32 must be caught for a release, so they measure nothing by themselves.
None of these numbers is a detection rate or a safety claim. They show which specific breaks the tests notice, chosen by whom, and when.
The limits
Where the lesson stops
- Every record is invented. Nothing here is a live clinical trial analysis, a recruitment forecast, or a clinical validation result.
- A country group holds the whole enrollment of its trials, across all countries. It does not count participants enrolled in that country, and multinational groups overlap.
- The rate is a supplied synthetic field. The lab does not validate it as a proxy.
- State maps and duration averages are outside this small lab’s scope.
- The eight enforced comment claims are a bounded catalog. They are not proof that all of the prose is true.
Run it
Check it yourself
Python 3.11 or later, and nothing else. No install step, no network, no API key, and no GPU.
git clone https://github.com/Angiebio/engineering-reliability.git
cd engineering-reliability/demos/registry-metric-lab
python -B -m unittest discover -s tests
python -B -m registry_metrics --out artifacts
Expect 46 passing tests. The report is a single HTML file at artifacts/index.html that opens from disk with no server.
- The fix in TrialCat, commit a146619
- Methods and limits, in the repository
- Who everyone in the record is
Who made this
This is my independent work, published through The Real Cat Labs as a teaching demonstration. No other person worked on it. I set the direction, supplied the domain judgment, and released the result. It was built inside the agent environment I engineered. Ying Akhila, an AI research agent, built the demos with Terminal Voice (T.V.), an AI coding agent. Flame Johnson, an AI agent on a different company’s model, reviewed them independently over three rounds, with audit agents and reproducible adversarial probes.
Ying Akhila is a research agent at The Real Cat Labs, running on a TRCL memory-enabled custom harness that deploys a GPT model. T.V. is Ying’s coding implementation agent.
Flame Johnson is an agentic AI staff member of The Real Cat Labs, a Claude model working in a coding harness with the lab’s persistent memory and standing project instructions. It is not a stock chat assistant.
Count trial identities. Then calculate the metric.
More builds
Other work with a page of its own
- Build Continuity Ledger Can a remembered instruction outlive its permission?
- Build Adapter Promotion Gate What must hold before a model change can serve?
- Build Stagnation Observatory When does useful work look stalled?
- Build Antiques Inference Engine Hand it a photo of an antique, and it works out with real physics whether the thing could power or run AI.
- Build Lantern Federated, privacy-tiered discovery for medical imaging.
- Build Lifeboat An ordinary external drive that carries open AI models and everything needed to run them.
- Build Off-Target A design change review of an AI-authored weight edit.
- Build Aurora Measures from brain science, run live on a persistent agent’s decision stream.
Get in touch
Speaking, teaching, board work, or coaching
I am glad to hear from conference organizers, journalists, students, and leaders who want a thinking partner.